
CoreWeave Trains DeepSeek-V3 in 2.02 Minutes on 8,192 GB300 GPUs
MLPerf Training 6.0: CoreWeave trains DeepSeek-V3 671B in 2.02 minutes, NVIDIA scales to 8,192 Blackwell GPUs, and GB300 NVL72 shows 1.6x speedups.
Read more
MLPerf Training 6.0: CoreWeave trains DeepSeek-V3 671B in 2.02 minutes, NVIDIA scales to 8,192 Blackwell GPUs, and GB300 NVL72 shows 1.6x speedups.
Read more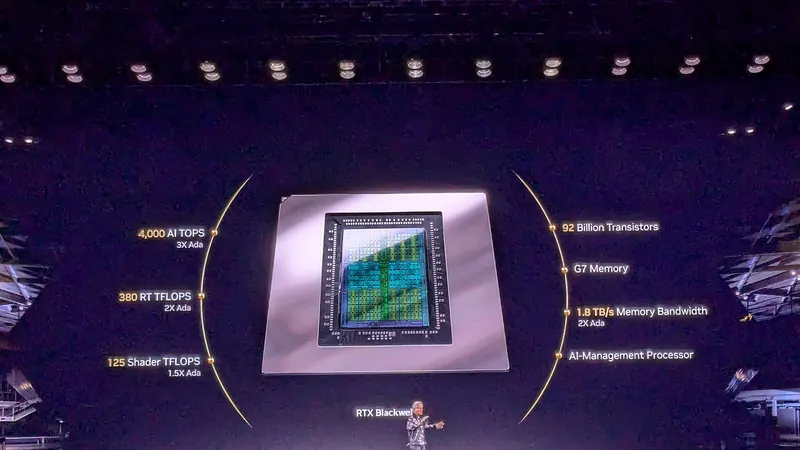
Architecture impact brief: NVFP4 E4M3 micro-block scaling, Blackwell Ultra's 15 petaFLOPS, and DeepSeek-R1 throughput trade-offs for accelerator buyers.
Read more
NVFP4 KV cache halves memory and doubles context budgets with sub-1% accuracy loss, but independent benchmarks are still pending.
Read more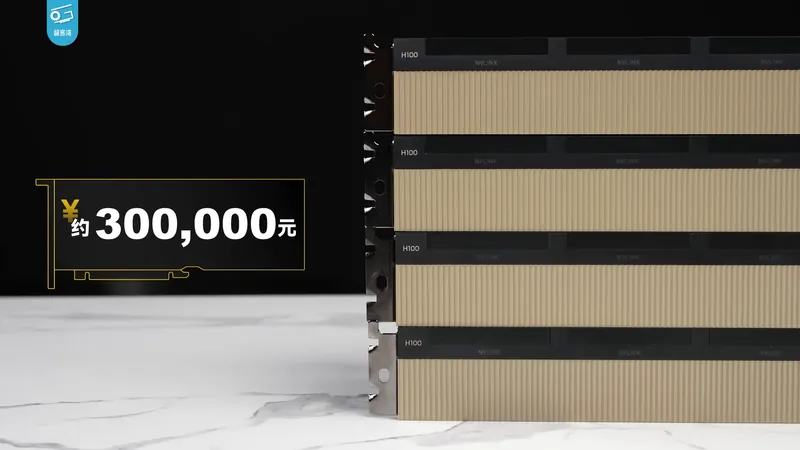
InferenceMAX v1 measures tokens/s, latency, and cost per token on AMD MI300X/MI325X and NVIDIA H100/H200/B200. Here are workload winners and software gaps.
Read moreOur Benchmarks hub translates raw lab telemetry from MLCommons (MLPerf Inference & Training) and independent suites like InferenceMAX into actionable engineering metrics: Time to First Token (TTFT), interactivity (tokens per second per user), Model FLOPs Utilization (MFU) and joules per token.
No single GPU wins every workload point. Compare Blackwell Ultra’s 5,842 tokens/s/GPU on DeepSeek-R1 using NVFP4 against InferenceMAX v1 AMD vs NVIDIA results across prefill, decode and Mixture-of-Experts routing.
Long-context reasoning models shift the bottleneck from matrix compute to HBM capacity and bandwidth. Learn how 4-bit NVFP4 KV-cache quantization halves memory footprint and doubles context budgets, or visit our Training vs Inference Buyer’s Guide.